Application performance monitoring
Tracing application requests end to end — from front-end devices through service calls to databases and message queues — and turning the spans into service maps, latency distributions and error analysis. In the product menu this is Performance Monitoring (the APM module).
How APM data gets in
Section titled “How APM data gets in”The shipping ingest path is OTLP, and both of its transports are accepted:
- OTLP/gRPC on port 4317 — the original path.
- OTLP/HTTP on the ordinary HTTP port (9200 by default), at the paths the
OpenTelemetry specification defines:
POST /v1/traces,/v1/logsand/v1/metrics, in either encoding the specification defines —Content-Type: application/x-protobuforapplication/json. The answer comes back in the encoding the request used.
sondar.otlp.enabled defaults to on, and the APM module reads the results back.
Point an exporter at HTTP like this:
export OTEL_EXPORTER_OTLP_PROTOCOL=http/protobufexport OTEL_EXPORTER_OTLP_ENDPOINT=http://<sondar-host>:9200export OTEL_EXPORTER_OTLP_HEADERS="authorization=<your collect token>"Note the port. The specification’s default for OTLP/HTTP is 4318, but the endpoint is configurable in every SDK and Sondar serves these paths on the port it already listens on — so there is no extra listener, TLS configuration or firewall rule to manage. 4318 on a Sondar host belongs to the agent, not the platform; see Concepts.
OTLP/JSON works too. It is what the OpenTelemetry JavaScript exporter
(@opentelemetry/exporter-trace-otlp-http) sends by default, so a browser or
Node service needs no protocol setting — only the endpoint and the header above.
Trace and span ids arrive as hex, as the OTLP specification writes them.
- Collect-token auth is required by default (
sondar.otlp.auth.required), so an exporter that reaches the OTLP port without a valid token is refused. The dead-port control separates auth from connectivity: a token problem and an unreachable port give different signals. - Span data is stored at the configured sampling rate while keeping each sampled trace complete; performance summaries are collected in full, so metric pre-aggregation is unaffected by sampling.
Auto-injection is not the shipping path. The claim that the agent
auto-injects into every application (JVM instrumentation by default) is not
what ships: auto-injection is
host-only and off by default (see the trace config panels in
agent-machines.md), and the LD_PRELOAD auto-injection half was removed
from the build. Application telemetry arrives over OTLP, from an exporter the
application (or its SDK) already runs. Do not promise magic zero-code
instrumentation on a fresh install.
Keeping an environment’s traces apart
Section titled “Keeping an environment’s traces apart”By default every environment’s traces share one set of indexes. To give an
environment its own (so production and staging can have different retention, or
be deleted separately), turn it on per environment by the value your services
send as deployment.environment:
-e sondar.apm.env.production.private_repo_enabled=trueThe environment’s indexes (tracing_spans_production, tracing_events_production
and the rest) are created when its first trace arrives, so nothing needs to exist
beforehand. Traces from environments without the setting keep going to the shared
indexes.
Grouping services
Section titled “Grouping services”Two things group services above the level of a single service, and they work differently on purpose. Service namespaces are derived from your telemetry and cost you nothing to set up; service groups are ones you define, and they may overlap.
Service namespaces — derived, one per service
Section titled “Service namespaces — derived, one per service”A service’s namespace comes from its own OpenTelemetry resource attributes:
service.namespace, or biz_system if you set that instead — biz_system
wins when both are present. Nothing needs configuring: instrument a service
with a namespace and it is grouped within about five minutes of first
reporting — the grouping runs every five minutes — whether or not it calls,
or is called by, any other service.
service.namespace is optional in OpenTelemetry, and a stock SDK does not set
it, so services with no namespace are the normal case rather than an error.
They are not hidden: the Service Namespace filter on every APM surface has an
entry called No service namespace that selects exactly them. It is worth
looking at — a service nobody has claimed is often a service nobody is
watching.
Two behaviors to know:
- A service belongs to one namespace. That follows from where the value
comes from: a service has one
service.namespace. If you want a service to appear in more than one place, use a service group. - A derived namespace is re-evaluated from your telemetry, rather than
being fixed the first time a service reports. Change
service.namespacein your exporter and redeploy and the service will move — but allow up to an hour for it to settle, because the check looks back over the last hour of data and your old namespace is still in that window. - Assigning a service by hand pins it, and pinning wins. Use
APM → Service Namespaces → Add Service when you want a
service somewhere its telemetry does not say. A pinned service stays where you
put it: editing your exporter will not move it, and even a
biz_systemattribute on the span is overridden. Pinned services are marked in that dialog, because two services sitting side by side in one namespace answer the same redeploy in opposite ways if one is pinned and the other is not. To hand a service back to its telemetry, remove it from the namespace — the next sync places it fromservice.namespaceagain.
Databases and message queues are grouped differently — by the services that call them — because shared infrastructure is not owned by one namespace the way a service is.
Service groups — curated, and allowed to overlap
Section titled “Service groups — curated, and allowed to overlap”A service group is a named query over service tags that you save and reuse. Where a namespace answers “who owns this service”, a service group answers anything else you want to ask: the services on one request path, the ones a team is on call for, everything on an old runtime.
A group is not limited to services. Databases and message queues are named the same way telemetry names them, so a group’s query selects those too — the Service Group picker appears on Services, Databases and Message Queues, and the same group applies on each. A group that names no queues shows none on the Message Queues page, rather than quietly showing all of them.
To make one, on APM → Services:
- Build a filter in the Search box. The tags available are Service Name, Service Type, Version and Env.
- Press Save and give it a name.
It then appears in the Service Group picker beside the Service Namespace filter.
Service groups behave differently from namespaces in three ways that matter:
-
They may overlap. Any number of service groups can contain the same service.
-
They narrow the namespace rather than replacing it. Choosing a namespace and a service group shows the services in both. Choosing one whose services are all in another namespace correctly shows nothing.
-
They stay legible. Selecting a service group writes its filter back into the Search box, so you can see what it means and edit it, and the page URL carries the filter so the view can be linked to.
-
They can be collapsed on the map. With a group selected on the service map, tick Collapse into one node to draw the whole group as a single node: calls between its own members become internal and disappear, and parallel calls to the same outside service are drawn as one edge. Throughput adds; error rate and latency are combined weighted by request volume, so a busy healthy member is not averaged against a quiet broken one.
-
They have a health. With a group selected, the filter bar shows the group’s status: the severity of its worst member. A group with a P1 firing inside it reads P1, not the average of its members and not the mildest alert it contains. A group whose members have no firing alerts reads Healthy, and nothing is shown until the query has finished — so the green state means “checked”, never “not yet asked”.
The zero-config default is unchanged: ALL namespaces and All services, which is what you get before you define anything.
Service owners — who to wake up
Section titled “Service owners — who to wake up”A namespace and a group both answer what is this. Neither answers who do I page, because a selection has no contact details. Owner is that separate attribute, and it is set per service.
The owner is one of your existing notification user groups — the same teams alert rules already notify — so assigning an owner does not create a second, parallel idea of who a team is.
On APM → Services, switch to the list view: the Owner column shows the owning team and lets you change it. Services with no owner read Unassigned, which is a real state rather than a blank: the list of unowned services is usually the first thing worth looking at. Clearing an owner is offered in the same place, because going back to unowned has to be as reachable as assigning.
Over the API:
curl -X PUT "$SONDAR/api/v1/apm/services/_owner:batch" \ -H "Content-Type: application/json" \ -H "X-Csrf-Token: $TOKEN" \ -d '{"services": ["checkout-web"], "ownerGroupId": 3}'Sending "ownerGroupId": null clears the owner. A service may have one owner.
Setting owners from your telemetry
Section titled “Setting owners from your telemetry”Instead of assigning every service by hand, a service can declare its team in its own OpenTelemetry resource attributes, and Sondar picks it up within a few minutes:
OTEL_RESOURCE_ATTRIBUTES="service.owner.name=payments-oncall"Sondar reads service.owner.name first — the name OpenTelemetry’s proposed
service.owner convention uses — then dt.owner and owner, so services
already tagged for Dynatrace work unchanged. The value must be the name of an
existing notification user group; matching ignores case when only one group
fits. Sondar never creates a group from an attribute, and a name that matches no
group, or more than one, is reported in the server log and not guessed.
An owner set this way shows auto beside it in the Owner column. Three rules decide what wins:
- A person’s choice always wins. Pick a team in the Owner column and the telemetry no longer changes it.
- Clearing hands it back. Clear the owner and the next sync takes it from the telemetry again.
- An owner is never taken away by omission. A service that stops sending the attribute, or names a group that does not exist, keeps its current owner — so renaming a group or one misconfigured deploy cannot strip ownership across your estate. A telemetry owner only moves to another group that exists.
Paging the owner
Section titled “Paging the owner”A user-group notification on an alert rule can also notify the owning team of
the service the alert is about — the rule’s service group-by. It is opt-in
per notification, adds the owner to the groups the rule already names (never
replacing them), and notifies a team once even if it is named twice. A service
with no owner adds nobody.
Turn it on with Also notify the service owner on a user-group
notification. With it on, the user groups themselves become optional: a
notification may page only the owning team. Over the API the same setting is
notifyServiceOwner: true on the notification.
Creating a service group over the API
Section titled “Creating a service group over the API”A service group is stored as a saved view, so the saved-view API creates and lists them — there is no separate group endpoint, and anything you make this way appears in the Service Group picker exactly as a group saved from the page does.
A saved view is treated as a service group when both are true:
- its view type is the service view, and
- its saved filter is not empty.
That second rule is the one that surprises people. A view saved with no filter selects every service, which is the whole estate rather than a cohort, so it is kept as an ordinary saved view and is deliberately not offered in the group picker.
curl -X POST "$SONDAR/api/v1/reports" \ -H "Content-Type: application/json" \ -H "X-Csrf-Token: $TOKEN" \ -d '{ "name": "checkout_path", "type": "app", "viewType": "apm_service", "time": {"preset": "m15"}, "spl": "mstats sumRate(service_requests_total)*60 as rpm by service, servicetype", "viewConfig": { "searchFilters": [ {"field": "service", "operation": "include", "value": ["checkout-web", "payments-api"]} ] } }'Every field above is required, and two of them are easy to lose:
namestarts with a letter, a number or an underscore, then letters, numbers, spaces and_ . - { }, up to 128 characters and not ending in a space — socheckout_path,checkout-pathandCheckout pathare all valid.typemust beappfor the view to appear in the Service Group picker. Leaving it out is refused with a 400 — “A saved view needs a type: app, event or visualization.” — and a view created with another type is saved but is not offered as a group.
time and spl are what the view replays when it is opened; the group picker
reads only the name and the filter.
The filter names services, but it selects any entity whose telemetry carries those tags — so a group can name a database or a queue in the same list, and the same group applies on all three pages.
The surfaces
Section titled “The surfaces”APM → Services — the service list: service name, type, request rate (RPM), hostname, kind, scope, error rate, Apdex, average and P50–P99 response times, max, instances, request and error counts. The topology view renders the discovered service map (the “View topology” entry from a service); nodes are services, edges are calls. Services are grouped by service namespace and by any service groups you define — see Grouping services.
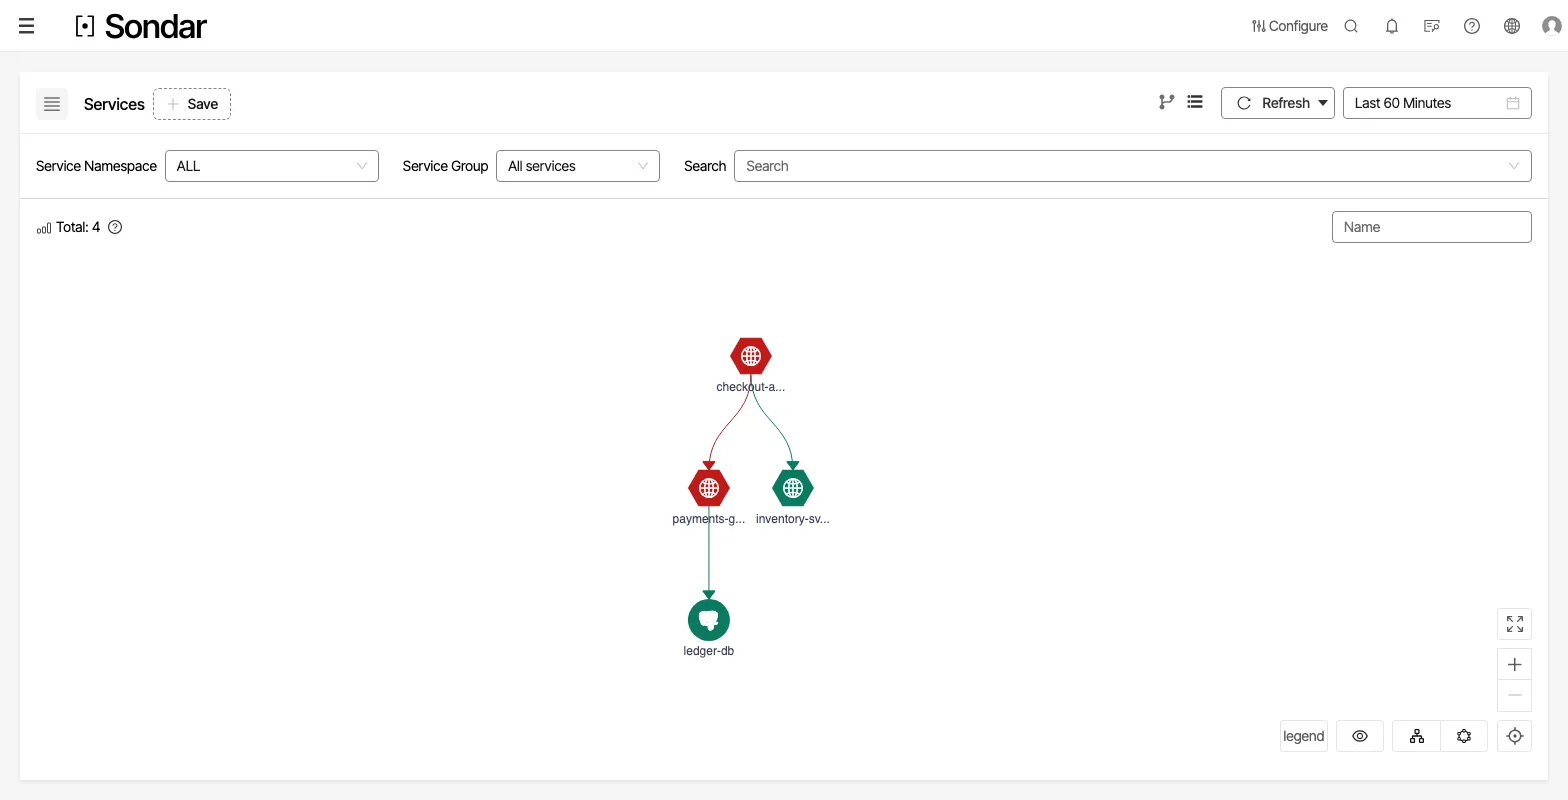
The topology the demo incident’s traces draw: checkout-api calls payments-gateway (red — the failing calls) and inventory-svc, and payments-gateway calls the ledger-db database. Services and edges come from CLIENT spans paired with the SERVER spans they call. The service list and topology are built as spans arrive: spans stamped two months in the past appeared under Trace but not here, so replay data from long ago will not draw a map. Captured September 29, 2026.
Trace — search by trace ID, or browse spans: time, service, operation, response time, status code, span type, scope name/version, attributes, error count, call times. A trace opens as the call tree — each span’s flow and execution time down the chain, the root-cause view.
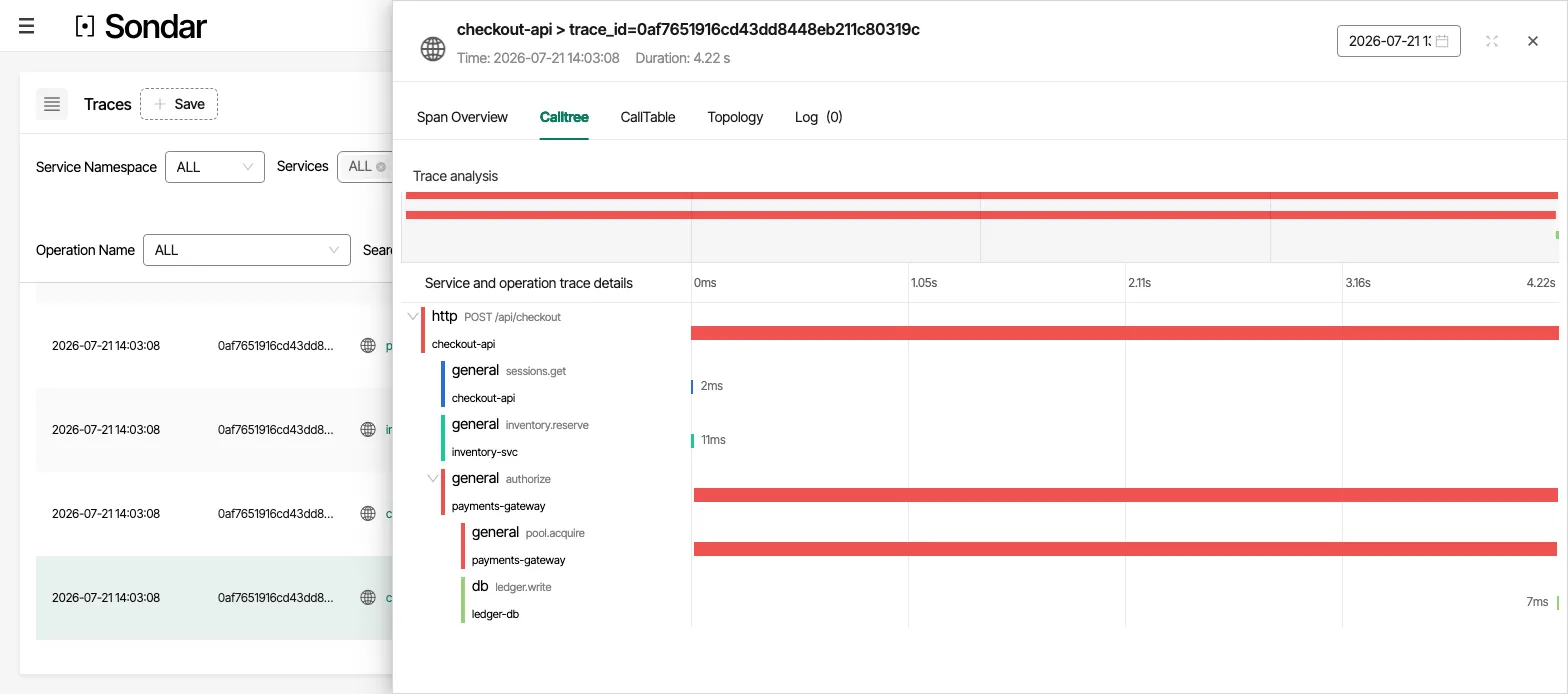
The call tree of one failed checkout from the demo incident, sent over OTLP. pool.acquire
waits about 4.2 seconds for a database connection; ledger.write, once it has one, takes 7 ms —
the database was never slow. Open a trace from its root span’s row to see the whole tree.
Captured September 29, 2026.
Config — the APM settings:
- Global config — latency bucket partitioning (affects response-time quantiles; finer buckets give more accurate percentiles, in milliseconds) and trace sampling.
- Service namespace and service config — which service namespaces exist, service display names, and per-service trace sampling.
- Trace sampling — store spans at a rate (0.0–1.0, default 1.0) while keeping sampled traces complete.
DB / MQ — the database and message-queue call analysis (DB type, call times, latency), the “which query is slow” surface.
Exception — collected error spans and their distribution.
Profiling (APM > Profiling, after Message Queues) — a CPU flame graph of what your services spend time on, and a table of the hottest functions. Filter by service, host or process, over any time range.
The samples come from sondar-profiling, the OpenTelemetry eBPF profiler
built into the Linux agent. It reads stacks from the kernel, so nothing is
injected into, or restarted in, the processes it profiles, and it needs no
language agent.
- Turning it on: in the agents’ Global Configuration, or one machine’s Custom Configuration (Agent configuration), under Trace Data Collection turn on trace collection and eBPF Profiling. It is off by default. The agent starts the profiler on each machine the setting covers.
- Where it runs: Linux on x86_64 or arm64, kernel 5.10 or later, with the
agent running as root (loading eBPF programs needs it). If the agent runs in a
container, that container needs the host’s PID namespace (
--pid=host) and privileges to load eBPF. With the Helm chart the agent is already privileged; the host PID namespace is off by default and needs--set sondard.daemonset.hostPID=true. On other platforms the toggle does nothing. - What it costs: the profiler and the eBPF agent together add about 160 MB of memory per machine, on top of the agent’s own ~185 MB. The agent’s memory budget defaults to 20% of the machine’s RAM (Global Configuration > Resource limits > RAM percent), and an agent over budget stops every collector on that machine — logs and metrics too — and shows as Sleep in the agent list, with the reason. On machines with less than about 1.7 GB of RAM, raise RAM percent before turning these on, or turn on Auto start there so the agent retries by itself.
- How a process is named: by its own
OTEL_SERVICE_NAME(orservice.nameinOTEL_RESOURCE_ATTRIBUTES) — the same name its traces use. Only those two environment variables are read, never the whole environment. - Native code (C, C++, Rust): named from the symbols the binary on that
machine already carries — its symbol table, or for a stripped library the
functions it exports, with C++ and Rust names shown readably (
Foo::bar). Nothing is sent anywhere to do it. Code with no symbol (a stripped binary’s internal functions) is shown as one “no symbols” row per library rather than guessed at. - Where it is stored: the
tracing_profilesrepo, one document per sampled stack, sent with the machine’s collect token.
The page needs the apm_profiling permission (Access Control > Roles).
Service Namespaces — the namespaces discovered from your telemetry, the services in each, and Add Service for moving a service between them. See Grouping services.
External Service — calls to services outside the traced set.
The key metrics
Section titled “The key metrics”- Apdex — the Apdex Alliance index of user satisfaction, 0–1: each
operation is satisfactory, tolerable (response between the threshold and
~4× it), or unsatisfactory;
(1×satisfactory + 0.5×tolerable) ÷ total. The threshold is what you configure as “tolerable”. - Error rate — failed requests as a percentage of total.
- Percentiles — P50–P99 response times per service and per operation.