Getting started
From a fresh install to your first alert, in six steps. Each step has a fuller page; this is the path through them.
If you are new to the data model, skim Concepts first — it is short and every page assumes it.
What the server needs
Section titled “What the server needs”Started with docker run, the server image has a fixed 4 GB heap and
reserves it at startup, so a default container settles at roughly 4.6 GB
resident while idle. That is sized for a working instance, not for a laptop
evaluation. The Helm chart and the Compose files set 2 GB instead, through
SONDAR_JAVA_OPTS.
It runs in far less if you tell it to. Set SONDAR_JAVA_OPTS — it is
appended after config/jvm.options, and the last -Xmx on the command line
wins, so you do not have to edit the file:
docker run -d --name sondar -p 9200:9200 \ -e SONDAR_JAVA_OPTS="-Xms1g -Xmx1g" \ -v sondar-data:/usr/share/sondar/var sondar:latestMeasured on the shipped image: with a 1 GB heap the container settles at about
1.4 GB resident and still starts, serves the UI and answers
/api/v1/readyz. Give it more when you start ingesting in earnest — the heap is
what searches and alert evaluation run in.
On a Linux host, raise vm.max_map_count first. The server’s storage
engine refuses to start below 262144, and stock Ubuntu ships 65530. It is a
setting of the Docker host — a container cannot change it — so run this once
on the host, and the second line to keep it across reboots:
sudo sysctl -w vm.max_map_count=262144echo 'vm.max_map_count=262144' | sudo tee /etc/sysctl.d/99-sondar.confWithout it the container exits with code 78 and a message saying exactly this. Docker Desktop and colima already set it high enough, so a laptop evaluation does not need it. On Kubernetes, set it on the nodes the server is scheduled on.
A fresh install occupies about 200 MB on disk before any data: roughly 150 MB of embedded database and 47 MB of installed apps. Your data directory grows from there.
The figures above are a footprint, not a capacity plan. How much you can ingest per node is a separate question and is not documented yet — do not read “runs in 1.4 GB” as “1.4 GB is enough for your workload.”
Running on Kubernetes
Section titled “Running on Kubernetes”The Helm chart installs one web pod and two data pods on the embedded metadata database (H2), which needs nothing else. The web pod serves the UI, the API and ingestion; the data pods store and search.
More than one web pod needs MySQL. On the embedded database every pod keeps its own copy of the metadata — settings, users, permissions, sessions — on its own volume, so a second web pod is a second, separate configuration. In our test, a second web pod saw none of the settings saved through the first and refused the same administrator the settings pages. With MySQL both pods share one store: a login and a saved setting work on either. So the chart refuses to install more than one web pod unless MySQL is turned on:
helm install sondar ./sondar \ --set mysql.enabled=true \ --set mysql.password=<choose one> --set mysql.rootPassword=<choose one>That runs MySQL inside the release, next to the pods.
The server refuses it too, outside the chart. A cluster started with plain Docker or from the tarball
can still put two web nodes on embedded H2, and a second node’s empty store used to accept a new
administrator account from anyone. Now only the elected master serves: any other web node on H2 answers
503 to everything except the health probes, fails its readiness check, and logs why. Set
node.web=false on the extra nodes, or point every web node at MySQL, then restart them.
Transport TLS is on by default. The chart generates a cluster CA and a node certificate on install, so the pods authenticate each other on 9300 and 9500 without any setup — see Securing the cluster ports for using your own certificates or turning it off.
With one web pod, it is also the cluster’s only master. While it restarts — an upgrade, a moved node — the UI, the API and ingestion are unavailable, and the data pods wait for it. Each background task on a data pod logs one warning when it loses the web pod, and the pod logs one line when the web pod answers again — not an error for every retry.
Three web pods on MySQL remove that outage. The chart makes every web pod master-eligible and requires a majority of them to elect a master, so a pod cut off from the others never becomes a second master. In our test, stopping the master pod got another one elected in about 3 seconds; the remaining web pods were serving again within 9 seconds and scheduled work resumed within 15. Logged-in requests to them kept being answered throughout, and an alert scheduled every minute never ran twice — it ran late once, or skipped one run when the pod running it stopped. A pod that has lost the cluster reports itself not ready, so traffic moves to the others.
helm install sondar ./sondar \ --set mysql.enabled=true \ --set mysql.password=<choose one> --set mysql.rootPassword=<choose one> \ --set sondardb.replicas.sondar-web=3Use one web pod or three — the chart refuses two, because two need each other to keep a master, which makes them less available than one. A fresh install of three web pods was ready in about two minutes in our test, and came back by itself after all three were deleted at once.
Upgrading an install made with an older chart needs one extra step: Kubernetes will not change how an existing StatefulSet starts its pods, and the chart now starts web pods together so they can elect a master. Delete the StatefulSets without their pods or data, then upgrade:
kubectl delete statefulset sondar-web sondar-data --cascade=orphanhelm upgrade sondar ./sondar -f <your values>IP geolocation set up through any web pod serves every pod: the chart keeps the database on a shared volume, and one pod downloads new builds for all of them.
If MySQL or a node goes away
Section titled “If MySQL or a node goes away”MySQL. Ingestion does not need it. HEC keeps accepting data through a MySQL
outage, using the tokens, indexes and sourcetypes the server had already loaded;
OTLP and the agents rely on the same loaded metadata, though our test measured
HEC. Everything else does need it: the UI shows a banner saying
the metadata database is not answering, and the API answers
503 MetadataStoreUnavailable with Retry-After: 5. Both come back by
themselves a few seconds after MySQL does. The web pods stay in the Service
throughout — readyz answers 200 with {"status":"degraded"} — because
every pod shares the one MySQL, and taking them all out would stop ingestion
too. A pod that has not reached MySQL since it started stays out.
While MySQL is down nothing can be changed: no new index, token or user, and a token revoked just before the outage keeps working until MySQL is back. A request that was already waiting on MySQL when its host disappeared can take up to the query timeout plus 30 seconds (90 by default) to answer; the server notices within about five seconds, and later requests are answered at once.
In our test a web node lost MySQL for two minutes while a sender wrote every
five seconds: with MySQL stopped every write was accepted (24 of 24, in at most
a quarter of a second) and every accepted line was searchable afterwards, the
API answered 503 within a tenth of a second, and the UI and API were back
within a second of MySQL; with its network cut instead, the one write in flight
at that moment waited 90 seconds and the rest were accepted. MySQL is the one component every web pod depends
on for the UI, so in production run it replicated.
A node. The shards it held keep working from their other copy, and the server then waits 5 minutes before building replacement copies on the remaining nodes. A node that comes back within that time — a restart, an upgrade, a rescheduled pod — gets its own copies back and only catches up on what it missed. After it, the copies are rebuilt elsewhere in full, and the node’s own are discarded when it returns. Elasticsearch waits one minute and Splunk’s cluster manager 60 seconds; Sondar waits longer because a copy that is still receiving logs can only be handed back before a rebuild starts, so an early rebuild copies whole shards for a node that was about to return.
The Monitoring Console shows it: Availability reads
Lost node: 2 copies wait (5 min) while copies wait, and Data → Shards
lists each with its reason (NODE_LEFT) and how long it has waited.
A rebuild needs disk room. When one node of three is lost, each of the other two takes on half as much data again, so if they are more than about half full the rebuild pushes them past 80%, the level at which the server stops placing copies on a disk. If a node will not come back, start the rebuild at once — signed in as an administrator (see The REST API):
curl -X PUT http://<host>:9200/api/v1/admin/internal/_all/_settings \ -H 'Content-Type: application/json' -H "X-Csrf-Token: <token>" -b <cookies> \ -d '{"index.unassigned.node_left.delayed_timeout": "0"}'then set it back to 5m the same way once the rebuild has started.
Serving HTTPS
Section titled “Serving HTTPS”Port 9200 serves plain HTTP unless you give the server a certificate. To serve HTTPS directly, put a PEM certificate and an unencrypted PEM private key in the container and point three settings at them:
docker run -d --name sondar -p 9200:9200 \ -v /etc/sondar/tls:/usr/share/sondar/config/tls:ro \ -e sondar.security.http.ssl.enabled=true \ -e sondar.security.http.ssl.certificate=/usr/share/sondar/config/tls/cert.pem \ -e sondar.security.http.ssl.key=/usr/share/sondar/config/tls/key.pem \ -v sondar-data:/usr/share/sondar/var sondar:latestThe server runs as the user sondar (uid 10001), so it must be able to read
both files. A private key is often root’s with mode 600; give it to that
user’s group first, on the host:
sudo chgrp 10001 /etc/sondar/tls/key.pem && sudo chmod 640 /etc/sondar/tls/key.pemOtherwise the container stops at once and says which file it cannot read.
The server then accepts TLS 1.3 and TLS 1.2 only, with forward-secret
AES-GCM and ChaCha20-Poly1305 cipher suites. TLS 1.1 and older, CBC-mode suites
and RSA key exchange are refused. Measured with openssl s_client on a
September 2026 build: TLS 1.3 negotiates TLS_AES_256_GCM_SHA384 and TLS 1.2
negotiates ECDHE-RSA-AES256-GCM-SHA384.
The Helm chart does not need this: it terminates TLS in its own gateway.
HTTPS from the server itself is still HTTP/1.1. It offers no HTTP/2 during
the TLS handshake (measured with openssl s_client -alpn h2,http/1.1: no
protocol negotiated), and browsers speak HTTP/2 only over TLS that offers it. Over
HTTP/1.1 a browser opens about six connections to a server, and the first page
loads over a hundred files, so they wait their turn. On your own machine that
wait is too short to notice. Across a real network it grows with the round-trip
time: at 40 ms it adds roughly a second to the first page. The Helm chart’s
gateway speaks HTTP/2, which removes the wait. For a single container serving
people over a network, put a reverse proxy that speaks HTTP/2 in front of port
9200 for the same effect.
A minimal nginx site for that, using the directives the Helm chart’s own gateway
uses (nginx 1.25.1 or later for http2 on):
server {    listen 443 ssl;    http2 on;    server_name sondar.example.com;    ssl_certificate     /etc/nginx/tls/tls.crt;    ssl_certificate_key /etc/nginx/tls/tls.key;    ssl_protocols       TLSv1.2 TLSv1.3;
    location / {        proxy_pass http://127.0.0.1:9200;        # nginx refuses request bodies over 1 MB by default; Sondar accepts up to        # 100 MB (file uploads, app and agent packages, large ingest batches).        client_max_body_size 100m;        proxy_set_header Host $host;        proxy_set_header X-Real-IP $remote_addr;        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;        proxy_set_header X-Forwarded-Proto $scheme;    }}
The proxy is for people’s browsers. Agents and OTLP exporters can keep sending to the server’s own ports.
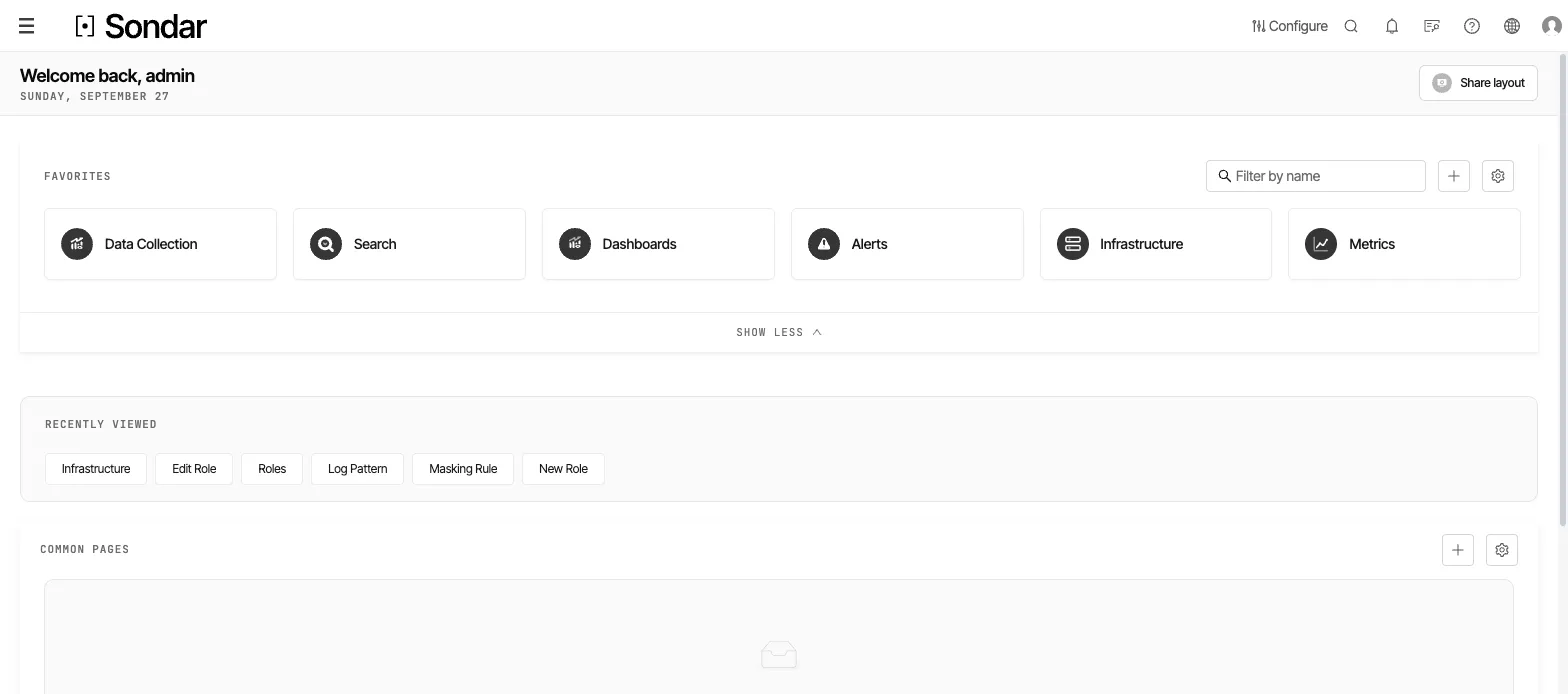
The home screen after install. Favorites are the surfaces most operators start from; the strip below records where you have just been. Captured September 27, 2026.
Try it first on sample data
Section titled “Try it first on sample data”Before connecting anything, you can explore a recorded incident. On Home, the Sample data card loads 67,057 events from a fictional shop’s checkout services, covering the 45 minutes up to the moment you click. Partway through, a connection pool runs dry and checkout starts failing. It is the same incident this site’s search examples use, so those queries return the same answers.
Load sample data creates, and marks as sample data:
- an index named
main, with the events in it; - the sourcetypes
checkout_api,db_poolandotel_spans, each with search-time field rules; - a dashboard, Checkout incident;
- four alert rules, one of them disabled.
It takes under a minute; keep the page open while it runs. The events arrive over HEC with a collect token made for the load and deleted afterwards, so collect tokens must be enabled. The card appears for users who may create indexes.
When it is done, the card links to a search, the dashboard and the alert
rules. Remove sample data deletes exactly what the load created, including
the index’s data, and nothing else. If the installation already has an index
named main that the sample did not create, nothing is loaded. Not now
hides the card in that browser.
1. Install the agent
Section titled “1. Install the agent”The agent is the machine-side collector. Open Data Collection (the Home tile, or Configure → Data Collection), then Agents ▸ Agents, and choose Add Agent:
- Manual install — the platform prints an install command; run it on the host (Linux or Windows). You can tag the machine now for later grouping.
- Auto install — the platform installs over SSH (host must be reachable and have SSH enabled).
- Docker / Kubernetes — a deploy command or a Helm chart for containers.
When the agent starts it reports back as Online. Full detail: Agent and machines.
2. Get data in — fastest with an app
Section titled “2. Get data in — fastest with an app”Pick one, and see something in ten minutes
Section titled “Pick one, and see something in ten minutes”Two routes. Take whichever describes you; both end at a screen worth showing someone.
A — you already run MySQL, Kafka, Redis or similar. Install that app and
run its collection template. Nothing to write. Taking MySQL: install MySQL
monitoring, create a collection task with the collect type mysql_tel, give
it host/port/credentials, and open the dashboard MySQL Overview — built,
populated, and yours. MySQL Slow Query Log and MySQL Error And General
Log come with the same app. The other databases work identically:
Database sources.
B — you want your own logs in. Point the agent at a file and send it to
the default index, which exists on a fresh install:
readers:  - fileset:      path: /var/log/myapp/*.log
senders:  - sondar:      repo: default      sourcetype: my_app      url: ["https://<your-sondar-host>:9200"]      token: "<collect token>"
Then search search2 repo="default" and you have your own data on screen. The
collect token comes from Configure → Access Control → Collection Tokens.
Route A gives you a dashboard faster; route B proves the platform against data you recognize. Neither needs anything from the rest of this page.
The quickest first collection is an integration app. Open the catalog, install the app for what you monitor — a database, a middleware, a web server, or plain host metrics — and run its collection template. The metrics, logs, dashboards and alert prototypes arrive together.
- Databases: Database sources
- Middleware (Kafka, RabbitMQ, ZooKeeper, …): Middleware
- Web servers (Nginx, Apache, HAProxy): Web servers and load balancers
- Hosts and Kubernetes: Host monitoring
No app for your data? Three other routes: point the agent at your logs (Log collection sources), let Sondar listen for pushed data (Listening collection), or upload a file (File upload).
3. Search
Section titled “3. Search”Open Search, pick an index, and type:
search2 index="_internal"_internal is created at install and the platform writes its own activity
there, so this returns rows on a brand-new instance before you have collected
anything. Once your own data is arriving, search that index instead:
search2 index="app_logs" "connection refused"Filter, group, and switch to the Visualization tab to see it as a chart. See Interactive search and, when you need more than one command, SonQL.
4. Save a dashboard
Section titled “4. Save a dashboard”A query worth keeping belongs on a dashboard. From the search, save it as a report and add it to a dashboard; then add more charts, set the refresh and time range, and leave it up. See Dashboards.
5. Set an alert
Section titled “5. Set an alert”An alert watches a search condition and notifies you. Create a rule (pick the metric or search, set the threshold and the severity), choose a notification channel — Slack, PagerDuty, email, and more — and confirm it fires. See Alerts and notifications.
6. Watch the platform itself
Section titled “6. Watch the platform itself”The Monitoring Console shows the platform’s own health — cluster availability, query load, shard and disk state — for the administrator. See Monitoring console.
Next, per role
Section titled “Next, per role”- SRE / on-call — Alerts, Search analysis, Log pattern recognition
- Platform owner — Indexes and field extraction, Metrics, User settings and notifications
- Service owner — APM; endpoint checks via the Heartbeat apps (Dial testing)
- Developer — Building apps and using the SDKs, Transformers