Metrics and resource groups
The metrics a customer monitors, and the resource groups that organize repos, metrics, dashboards and alert rules into a hierarchy.
Resource groups
Section titled “Resource groups”A resource group is a label you attach to a resource — a repo, a metric, a dashboard, an alert rule — so that the list pages can be navigated as a folder tree instead of a flat table. A resource can belong to more than one group, and groups nest to several levels.
They exist to replace searching: name your groups after teams, environments or service namespaces, and every list that carries the group column becomes a tree you can collapse.
Where they appear
Section titled “Where they appear”Grouping is offered wherever a resource list shows the Groups column and an
edit affordance. Measured surfaces: Configure → Index, Configure → Sourcetype,
Configure → Field → Extract Fields, Data Collection → Agents ▸ Parse Templates,
Metrics → Metric, object management (/metric/objectManage), and alert rules. Repos, metrics and
objects show the group directly in the row and can be moved between groups from
the list.
The group tree
Section titled “The group tree”Groups form a tree. A group has:
- a name (required, unique among its siblings);
- a description;
- a parent directory (groups nest to several levels);
- a position among its siblings — a group can be moved, and moving respects order, so the tree stays sortable by hand rather than alphabetically.
Groups are created, edited, deleted and re-parented from the tree, and bulk deletion/movement is supported. Deleting a group removes the grouping, not the resources in it.
Associating resources
Section titled “Associating resources”Resources are added to groups either at creation (a repo created with “group selection” appears under each chosen group) or later from the list page’s Groups edit. The relation is per-resource: editing a resource’s groups adds or removes its group memberships without touching other resources. Bulk group editing is supported on the list pages.
A resource with a favorite (Favorite) pin sorts to the top of its group.
Metrics
Section titled “Metrics”Metrics are the numeric monitoring data collected from hosts, middleware and third-party systems. Sondar stores them as its own metric repos and exposes them through five surfaces:
| surface | route | permission |
|---|---|---|
| Metric management | /metric/metricManage | metric |
| Metric Explorer | /metric/browse | metric_view |
| Object management | /metric/objectManage | target |
| Generate Metric | /metric/genRule | metric to open the page; the rules listed are filtered by metric_gen_rule; alert_rules to edit |
| Downsampling Metrics | /metric/downsampling | metric_downsampling_rule |
The permission column is the function id; see roles-and-permissions.md for what a function grants and how roles bundle them.
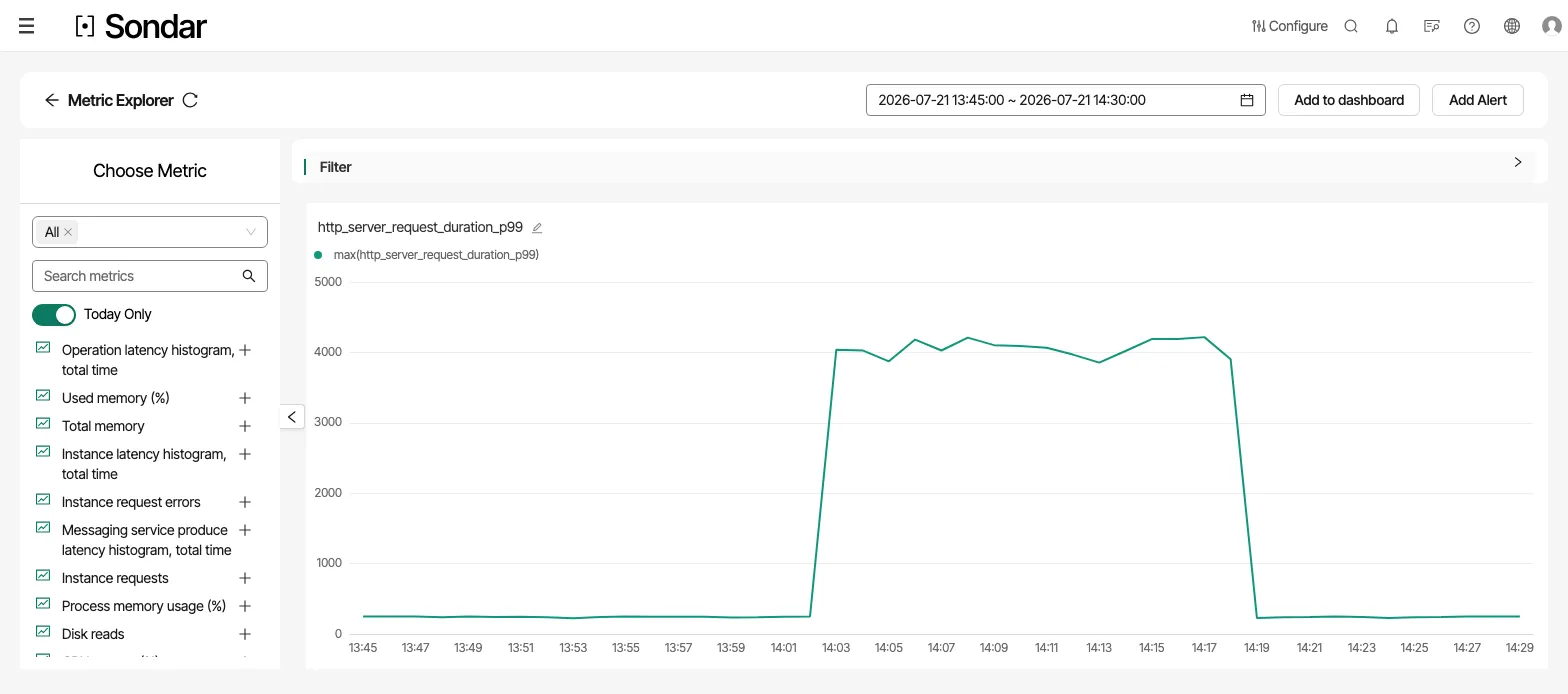
Metric Explorer over the demo incident, 13:45-14:30 UTC: max of p99 request duration, sent over OTLP as http.server.request.duration.p99. About 200 ms, then about 4,100 ms from 14:03 while the payments pool is exhausted, back at 14:18. The Filter panel is collapsed to give the chart the room. Captured September 30, 2026.
Where the data comes from
Section titled “Where the data comes from”Metrics are collected by the agent (the same machine agent that ships logs) and arrive through a metric collection task — configured under Data Collection → Collection Tasks, which delivers the agent and the collection profile in one flow. Metric data can also be synchronized in from third-party sources; the metric list has a global synchronization policy (manual or on a schedule, with a target repo and frequency) and its records land in task management.
A metric is identified by its key (a unique identifier) and carries a name, labels, a target type, a unit, an owner and a level. Keys are permanent: you can edit a metric but not its key.
Metric management (/metric/metricManage)
Section titled “Metric management (/metric/metricManage)”The list of every metric. The left rail is the grouping tree (default and user-created groups; a metric can belong to many). The default “Show only metrics with data for today” filter is on — turn it off to see every metric, not just the live ones.
Columns: metric name, labels, target type, unit, groups, origin, key, status, owner, type, level, calculation, created time, updated time.
Row and batch operations: create (hand-built metrics are supported), edit (keys immutable), import (manual or bundled with an app) and export (single, selected or all), delete, reassign owner, authorize, and group edits. Preview jumps to Metric Explorer for that metric.
Metrics you send over OTLP join this list through a sync. Auto Sync
runs every minute by default and registers the metric names that arrived in the
last five minutes, so a live exporter’s metrics appear on their own within a
minute or two; the OTLP name keeps its words, with dots as underscores
(http.server.request.duration becomes http_server_request_duration).
Data sent with older timestamps — a backfill or a replay — is outside that
window: run Manual Sync with its index and time range. Both are under the
Metric Manage page’s sync settings.
Metric Explorer (/metric/browse)
Section titled “Metric Explorer (/metric/browse)”The analysis surface. Pick one or more metrics (by tree or search), and for
each configure an aggregation (avg, sum, max, min, rate, count,
distinct_count, first, last, percentiles, stdev/stdevp,
earliest/latest, …), a unit, filters (tag = / != / exists / is
null / in / not-in, combined AND/OR), and group-by fields. Charts update
live; the configured chart can be saved to a dashboard.
A metric opens on the aggregation its catalog entry lists first: a per-second
rate (sumRate) for a counter such as service_requests_total, a percentile
(hperc) for a latency histogram, and avg for a gauge. Pick another from the
aggregation menu and it is kept, including when you switch to another metric
that supports it.
Metric functions are applied per metric, in a stack:
| function | what it does |
|---|---|
| Rate | rate of change per second / minute / hour / day; negative values become zero or are preserved |
| Anomalies | flag points that do not match the metric’s own recent behavior — green band = expected range, red points = anomalies. The series is decomposed into trend, season and remainder, so a Monday-morning peak is not an anomaly; the threshold comes from the shape of the observed tail rather than a fixed multiple of the standard deviation, so a heavy-tailed latency metric is not flagged constantly. Settings: Risk (roughly how often a false alarm is acceptable), Persistence (how many consecutive points must be out of range), Period (the seasonal cycle, in points), and whether to flag drops as well as spikes |
| Forecast | project the metric forward and answer when it crosses a threshold — dotted line for the projection, band for the expected range. Give it the threshold you care about and it reports a crossing date with an interval around it, or says plainly that no crossing is projected. The forecaster is chosen per series by backtesting several against that series’ own history. Settings: Horizon, Threshold, Direction (crossing from below or above), Persistence |
| Outliers | find the members of a group that do not match their peers — the one host behaving unlike the other forty, which is a different question from Anomalies (that one compares a series to its own past). Uses the median and a robust spread, so several bad members cannot hide each other by dragging the average. Settings: Tolerance, and whether to flag members below the group as well as above |
| Timeshift | shift a metric in time (minute to year) — the way year-on-year and month-on-month comparisons are built (offset the metric and subtract) |
| Arithmetic | log2, log10, absolute value |
| Exclusion | null-out or clamp points at a threshold — four variants (null below / null above / clamp below / clamp above) |
| Count | count non-zero values per moment, or non-null values per moment (for grouped series: “is any sequence zero/missing at this point?”) |
| Rollup | re-aggregate each series at a coarser interval (avg/sum/count/max/min/rate/increase/latest) |
| Sort | keep the top N series by an aggregation (avg/sum/min/max/last), ascending or descending |
Object management (/metric/objectManage)
Section titled “Object management (/metric/objectManage)”An object is what metrics describe — a host, a service, a target — formed from collected metrics by rules. The list shows object name, target types, the metric count under each object, groups, IP and port. Opening an object shows its metrics and related context. This is also where objects are grouped and linked, the basis for per-object views and for alerting on an object’s metric rather than on a bare query.
Health, capacity analysis and service-level analysis are not in the shipped
product. These derived surfaces have no shipped frontend. The health wall
and health templates exist as server
controllers, but the app that rendered them (sondar-business-health) was
deleted from the product on 28 Sep 2026 — there is no screen for them. Do not
promise health scoring or capacity forecasting.
Generate Metric (/metric/genRule)
Section titled “Generate Metric (/metric/genRule)”Turns a search into a metric — the query defines a metric key/tag set, an
aggregation (avg/max/min/rate/count/distinct_count/earliest/
latest/stdev/stdevp) and a schedule. The generated metric then appears in
the metric list and is browsable like any collected metric.
Downsampling Metrics (/metric/downsampling)
Section titled “Downsampling Metrics (/metric/downsampling)”Cost control for metric storage. A downsampling rule aggregates an index’s metric series at a coarser granularity — 5-minute, 1-hour or 1-day — into a downsampling index, with a storage limit and ILM phase for the result. Old raw series can then be dropped from the hot index while the coarser history stays queryable. Rules are listed per index, can be enabled/disabled, and import and export.
A metric’s unit comes from a fixed catalog (general, time, data IEC, data rate, throughput, length, area, mass, velocity, volume, energy, temperature, pressure, force, flow, angle, acceleration, radiation, concentration).
A note for anyone with older dashboards. The catalog used to carry a second time family whose labels were the Chinese unit names, and it was the one place a Chinese string could reach an English metric chart. It is gone from the picker, and the old
timeZhunit codes are aliased to the Englishtimefamily — so a dashboard saved with one keeps working and now renders in English. Nothing to change on your side.
Getting it right the first time
Section titled “Getting it right the first time”- Name metrics with their key in mind — keys are immutable.
- Group as you create — repos and metrics accept groups at creation, and retro-fitting every row later is the slow way.
- Downsample before you need to — 5-minute vs 1-day history is a storage decision that compounds; a rule applied early costs less than one retrofitted to a full index.
- The “today only” filter lies on purpose — a metric with no data today is hidden by default. When investigating a silent alert, turn it off.